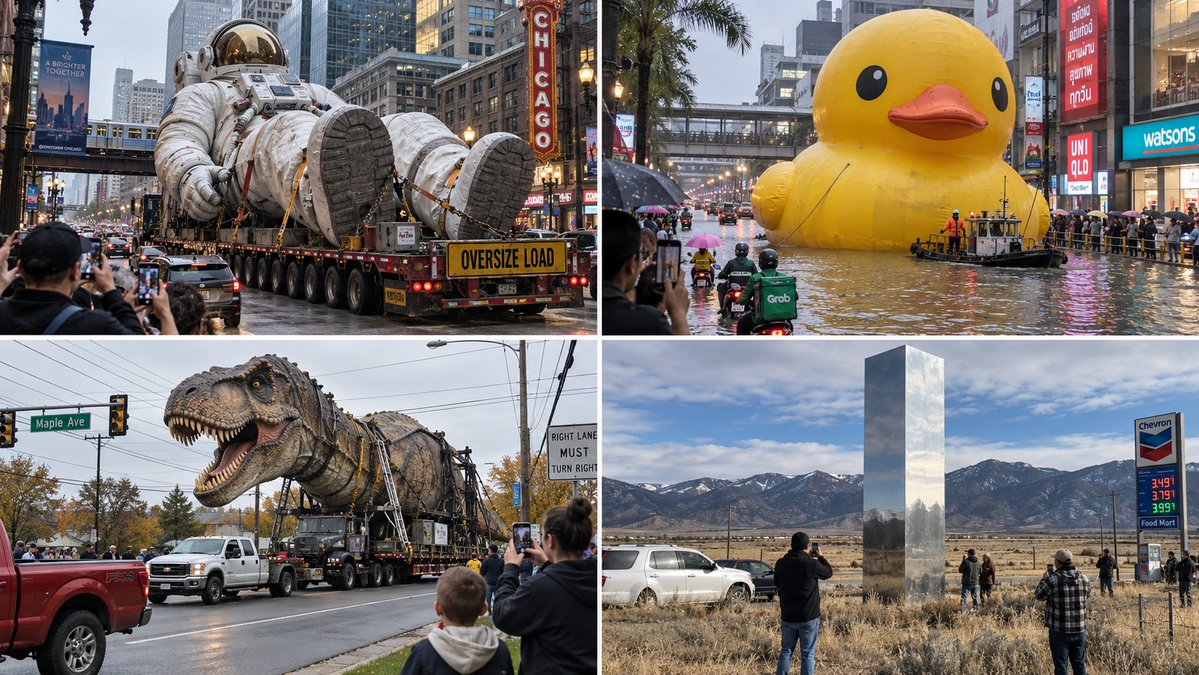
PROMPT RECORD · 公开作品详情
2x2 网格,16:9,AI 自选不同的病毒式传播话题,从零开始创作,不要当作编辑处理:
公开 AI 图像创作记录,包含原图、提示词、使用模型、作者、标签与来源。
- 使用模型
- Seedance 2.5
- 创作者
- @Gdgtify
- 发布时间
- Fri Sep 25 11:29:00 +0000 2026
- 图片数量
- 1 张
完整提示词
源提示词按原始换行与标点完整保留2x2 grid, 16:9, AI picks different viral topics, create from scratch, do not treat as edit:
class ViralEyewitnessScene:
def __init__(self, topic):
self.topic = topic
self.subject_form = infer_physical_manifestation(topic)
self.event_type = infer_plausible_public_sighting(topic)
self.environment = infer_best_everyday_environment(topic)
self.capture_viewpoint = infer_bystander_viewpoint(topic)
def subject_logic(self):
return {
"scale": "unexpectedly large, notable, rare, or bizarre",
"presence": "physically grounded and believable",
"condition": "real-world wear, transport hardware, practical constraints"
}
def environment_logic(self):
return {
"setting": self.environment,
"public_context": "ordinary daily life continues around it",
"supporting_details": [
"traffic", "signage", "weather", "infrastructure",
"scale references", "bystanders", "vehicles"
]
}
def capture_logic(self):
return {
"camera_style": "candid, viral, observational",
"viewpoint": self.capture_viewpoint,
"framing": "slightly imperfect, believable, non-cinematic",
"mood": "surprised eyewitness realism"
}
def render(self):
return f"""
Render {self.subject_form} in a surprising but plausible
public/transport scenario, in {self.environment},
captured from {self.capture_viewpoint},
with documentary realism and viral-image energy.
"""提示词译文
译文与源提示词分开显示,不替代原文2x2 网格,16:9,AI 自选不同的病毒式传播话题,从零开始创作,不要当作编辑处理:
class ViralEyewitnessScene:
def __init__(self, topic):
self.topic = topic
self.subject_form = infer_physical_manifestation(topic)
self.event_type = infer_plausible_public_sighting(topic)
self.environment = infer_best_everyday_environment(topic)
self.capture_viewpoint = infer_bystander_viewpoint(topic)
def subject_logic(self):
return {
"scale": "unexpectedly large, notable, rare, or bizarre",
"presence": "physically grounded and believable",
"condition": "real-world wear, transport hardware, practical constraints"
}
def environment_logic(self):
return {
"setting": self.environment,
"public_context": "ordinary daily life continues around it",
"supporting_details": [
"traffic", "signage", "weather", "infrastructure",
"scale references", "bystanders", "vehicles"
]
}
def capture_logic(self):
return {
"camera_style": "candid, viral, observational",
"viewpoint": self.capture_viewpoint,
"framing": "slightly imperfect, believable, non-cinematic",
"mood": "surprised eyewitness realism"
}
def render(self):
return f"""
Render {self.subject_form} in a surprising but plausible
public/transport scenario, in {self.environment},
captured from {self.capture_viewpoint},
with documentary realism and viral-image energy.
"""