PROMPT RECORD · 公开作品详情
我注意到 AI 图像模型处理提示词的方式有一些特点:基于 CLIP 的文本编码器会将你的文字切分成离散的 token(词元)。当你的提示词是一…
公开 AI 图像创作记录,包含原图、提示词、使用模型、作者、标签与来源。
- 使用模型
- None
- 创作者
- @FadyEid
- 发布时间
- Fri Apr 03 23:35:43 +0000 2026
- 图片数量
- 1 张
完整提示词
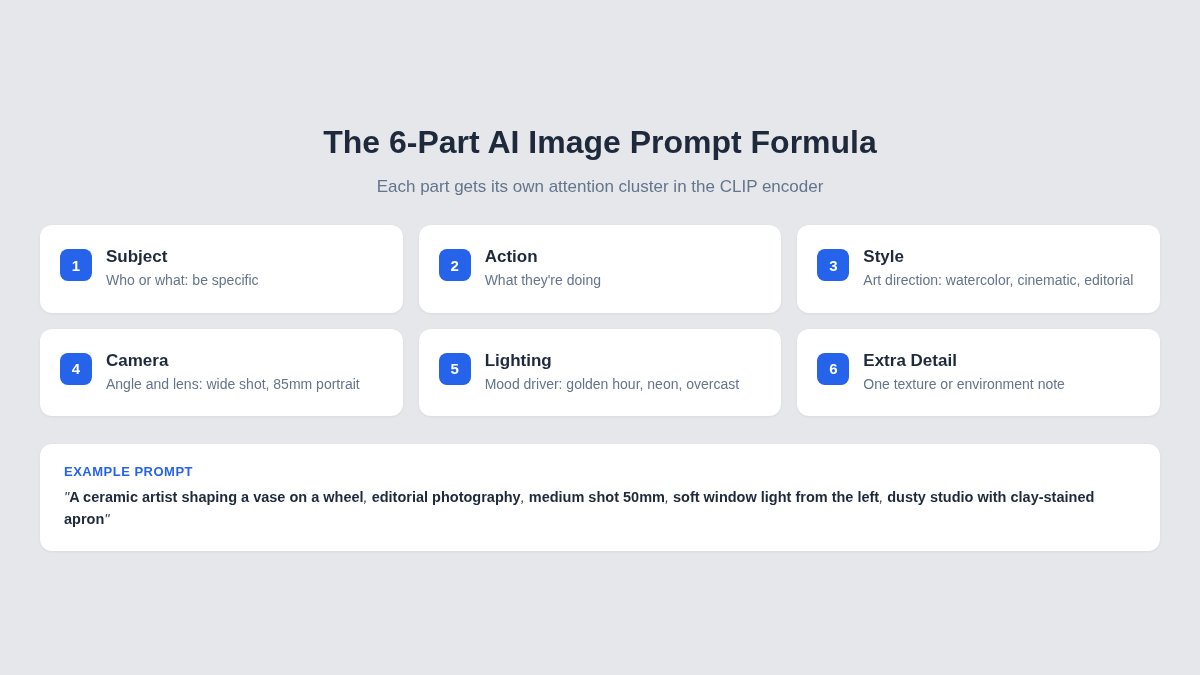
源提示词按原始换行与标点完整保留I noticed something about how AI image models process prompts: CLIP-based text encoders tokenize your words into discrete chunks. When your prompt is one long sentence, key details compete for the same attention weight. The model guesses what matters. A structured prompt fixes that. Each concept gets its own attention cluster. I've been using a 6-part formula and the results are noticeably sharper: 1- Subject: who or what (be specific) 2- Action: what they're doing 3- Style: art direction (watercolor, cinematic, editorial) 4- Camera: angle and lens (wide shot, 85mm portrait) 5- Lighting: mood driver (golden hour, neon, overcast) 6- Extra detail: one texture or environment note Example: "A ceramic artist shaping a vase on a wheel, editorial photography style, medium shot 50mm, soft window light from the left, dusty studio with clay-stained apron" Swap one part at a time to see what each controls. #AIImages #PromptEngineering #AITips #GenerativeAI #CreativeAI
提示词译文
译文与源提示词分开显示,不替代原文我注意到 AI 图像模型处理提示词的方式有一些特点:基于 CLIP 的文本编码器会将你的文字切分成离散的 token(词元)。当你的提示词是一整句长句子时,关键细节会争夺相同的注意力权重,模型只能猜测哪些内容更重要。 而结构化的提示词可以解决这个问题——每个概念都会拥有独立的注意力聚类。 我一直在使用一个 6 部分公式,效果明显更清晰: 1- Subject(主体):是谁或是什么(要具体) 2- Action(动作):在做什么 3- Style(风格):艺术方向(watercolor 水彩、cinematic 电影感、editorial 编辑摄影) 4- Camera(镜头):角度与焦距(wide shot 广角、85mm portrait 85mm 人像) 5- Lighting(光线):情绪驱动(golden hour 黄金时刻、neon 霓虹、overcast 阴天) 6- Extra detail(额外细节):一个质感或环境描述 示例:"A ceramic artist shaping a vase on a wheel, editorial photography style, medium shot 50mm, soft window light from the left, dusty studio with clay-stained apron" 每次只替换一个部分,就能看出每个要素控制的是什么。 #AIImages #PromptEngineering #AITips #GenerativeAI #CreativeAI